diff --git a/doc/api/content/algo/getting-started/development.md b/doc/api/content/algo/getting-started/development.md
index 1ffca3750..934d28424 100644
--- a/doc/api/content/algo/getting-started/development.md
+++ b/doc/api/content/algo/getting-started/development.md
@@ -133,5 +133,8 @@ Breakpoint 1 (algo_template.cpp:45) pending.
Starting program: /sparkbin/sparkd run
```
-If your editor supports debugging over the ssh protocol you can configure and start sshd from inside the container.
+If your editor supports debugging over the ssh protocol you can start sshd from inside the container.
+## Next
+
+Continue to [Algo Lifecycle](/algo/ref/lifecycle) to learn how Algos are created and respond to external evens in Spark.
diff --git a/doc/api/content/algo/getting-started/overview.md b/doc/api/content/algo/getting-started/overview.md
index 87875f3a0..3b23e7f4d 100644
--- a/doc/api/content/algo/getting-started/overview.md
+++ b/doc/api/content/algo/getting-started/overview.md
@@ -5,7 +5,7 @@ weight = 0
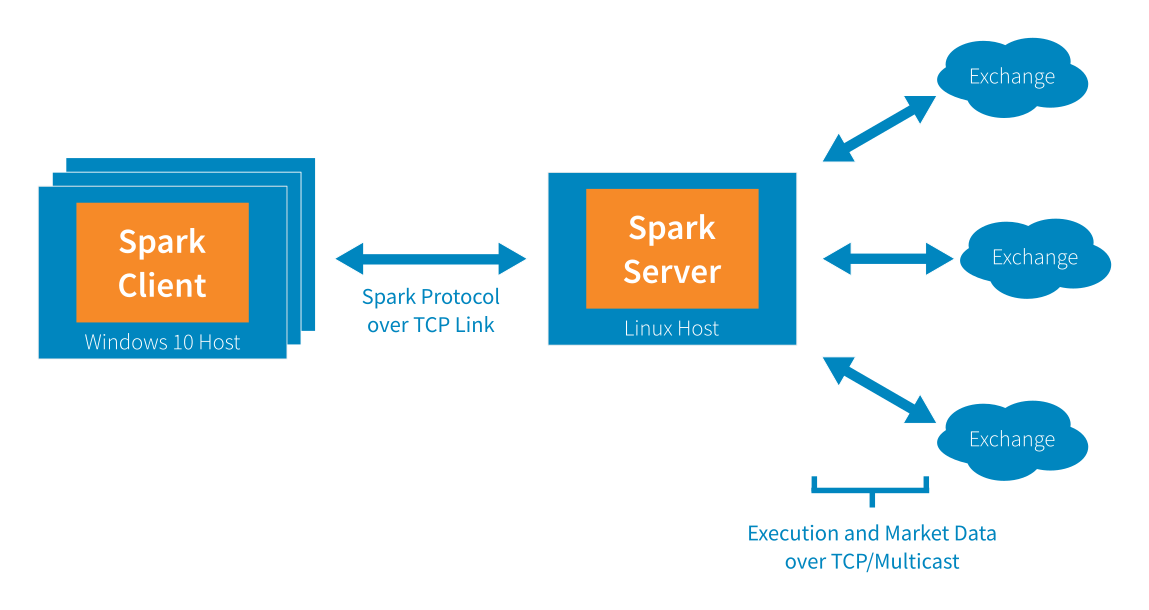
Spark consists of a client UI ([Spark Client](https://www.bluetradingsystems.com/bts-spark#ladder-algo-screen)), a high performance professional futures front end, connected via our proprietary protocol over TCP to our Spark Server, which in turn connects to execution venues via their native protocols (typically FIX/TCP for execution and some proprietary protocol over UDP multicast for market data).
-
+
## What is the Spark Algo SDK?
diff --git a/doc/api/content/algo/getting-started/testing.md b/doc/api/content/algo/getting-started/testing.md
deleted file mode 100644
index 033fa787d..000000000
--- a/doc/api/content/algo/getting-started/testing.md
+++ /dev/null
@@ -1,6 +0,0 @@
-+++
-title = "Testing"
-weight = 4
-+++
-
-* Test your algo
diff --git a/doc/api/content/algo/ref/lifecycle.md b/doc/api/content/algo/ref/lifecycle.md
index 7b0b37456..9533aec5e 100644
--- a/doc/api/content/algo/ref/lifecycle.md
+++ b/doc/api/content/algo/ref/lifecycle.md
@@ -3,4 +3,30 @@ title = "Algo Lifecycle"
weight = 0
+++
-todo
+Spark Algos are registered when Spark Server starts and move though several states as they are activated and become live on the market.
+
+## Load and Register
+
+On startup Spark Server loads all plugins listed in the /sparkbin/plugins directory and calls an exported function named `init_spark_plugin` with the following signature.
+
+```cpp
+extern "C" void init_spark_plugin(bts::SparkServices &serv) { }
+```
+
+Your Algo must export this function and use the bts::SparkServices instance to register your Algos. You can define more than one Algo type in a single plugin. In that case your init_spark_plugin function should register all available Algos.
+
+To register an Algo construct an instance of `DynamicOrderDescriptor`
+
+## Construction
+
+
+## Before Launch
+optional but suggested
+
+## Launch / Launch Attached
+required, latency sensitive
+
+## Update
+
+
+Every Spark Algo implements
diff --git a/doc/api/static/images/API.png b/doc/api/static/images/API.png
new file mode 100644
index 000000000..e53f95aaf
Binary files /dev/null and b/doc/api/static/images/API.png differ
diff --git a/doc/api/static/images/logo.svg b/doc/api/static/images/logo.svg
new file mode 100644
index 000000000..d9d0f4b0c
--- /dev/null
+++ b/doc/api/static/images/logo.svg
@@ -0,0 +1,2 @@
+
+
diff --git a/doc/api/templates/index.html b/doc/api/templates/index.html
index 41d5a54c8..561dde3cd 100644
--- a/doc/api/templates/index.html
+++ b/doc/api/templates/index.html
@@ -20,7 +20,7 @@
 +
 ## What is the Spark Algo SDK?
diff --git a/doc/api/content/algo/getting-started/testing.md b/doc/api/content/algo/getting-started/testing.md
deleted file mode 100644
index 033fa787d..000000000
--- a/doc/api/content/algo/getting-started/testing.md
+++ /dev/null
@@ -1,6 +0,0 @@
-+++
-title = "Testing"
-weight = 4
-+++
-
-* Test your algo
diff --git a/doc/api/content/algo/ref/lifecycle.md b/doc/api/content/algo/ref/lifecycle.md
index 7b0b37456..9533aec5e 100644
--- a/doc/api/content/algo/ref/lifecycle.md
+++ b/doc/api/content/algo/ref/lifecycle.md
@@ -3,4 +3,30 @@ title = "Algo Lifecycle"
weight = 0
+++
-todo
+Spark Algos are registered when Spark Server starts and move though several states as they are activated and become live on the market.
+
+## Load and Register
+
+On startup Spark Server loads all plugins listed in the /sparkbin/plugins directory and calls an exported function named `init_spark_plugin` with the following signature.
+
+```cpp
+extern "C" void init_spark_plugin(bts::SparkServices &serv) { }
+```
+
+Your Algo must export this function and use the bts::SparkServices instance to register your Algos. You can define more than one Algo type in a single plugin. In that case your init_spark_plugin function should register all available Algos.
+
+To register an Algo construct an instance of `DynamicOrderDescriptor`
+
+## Construction
+
+
+## Before Launch
+optional but suggested
+
+## Launch / Launch Attached
+required, latency sensitive
+
+## Update
+
+
+Every Spark Algo implements
diff --git a/doc/api/static/images/API.png b/doc/api/static/images/API.png
new file mode 100644
index 000000000..e53f95aaf
Binary files /dev/null and b/doc/api/static/images/API.png differ
diff --git a/doc/api/static/images/logo.svg b/doc/api/static/images/logo.svg
new file mode 100644
index 000000000..d9d0f4b0c
--- /dev/null
+++ b/doc/api/static/images/logo.svg
@@ -0,0 +1,2 @@
+
+
diff --git a/doc/api/templates/index.html b/doc/api/templates/index.html
index 41d5a54c8..561dde3cd 100644
--- a/doc/api/templates/index.html
+++ b/doc/api/templates/index.html
@@ -20,7 +20,7 @@